CenterPoint Energy / Service 360 multi-agent Copilot · 2026
Designing AI agents for Electric Service
Connecting fragmented electric service work through coordinated AI assistance—from discovery and product definition to a targeted production release.
- Role
- Lead UX & Technical Product Analyst
- Contribution
- Discovery, research, stories, journeys & flows
- Partner
- Through Bowdark
- Release
- Production for a targeted user group
01 / OVERVIEW
From fragmented work to coordinated assistance
I led discovery and UX for CenterPoint Energy’s Electric Service AI agents, translating complex service-delivery workflows into assistance that helped consultants understand their work, find operational guidance, prepare documentation, and respond to delays. Through Bowdark, I owned discovery, user interviews, research, user stories, journeys, and user flows, alongside technical product analysis.
Working with business stakeholders and engineering, we brought all agents into production for a targeted user group. Success at this stage centered on milestone delivery, data quality, testing results, and rollout. Longer-term operational impact remained to be measured.
The opportunity was not simply to add chat to an existing process. It was to preserve the service-request context across distinct forms of assistance, so consultants could understand the information behind an answer and the next action available to them.
- SmartStart · Orient
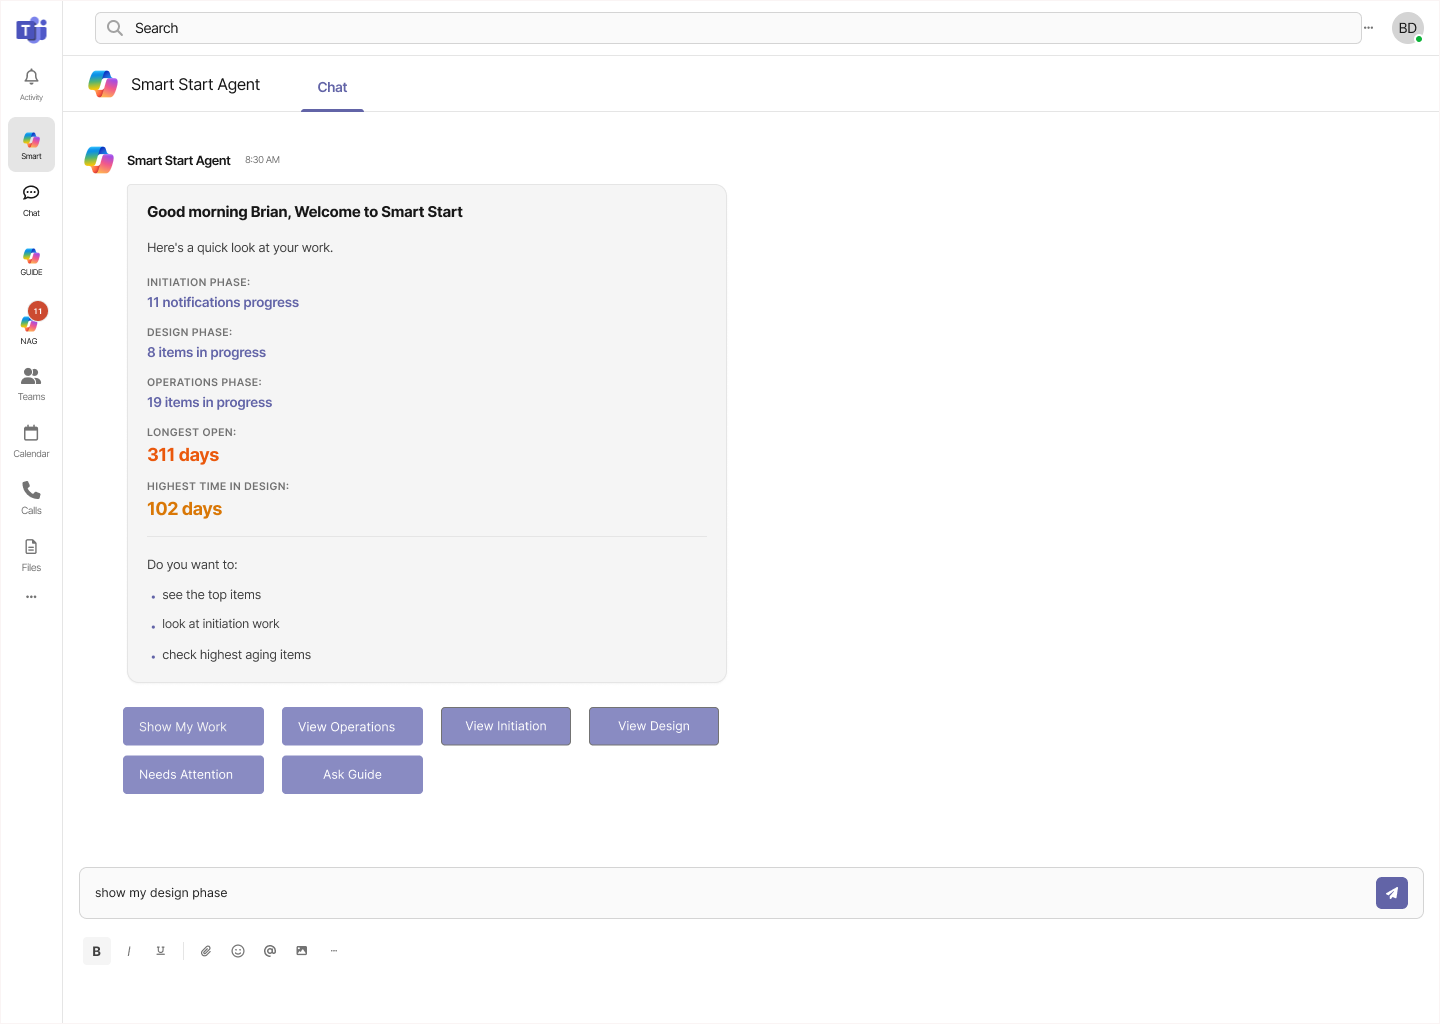
- Bring daily work, status, and priorities into the consultant’s starting experience.
- GUIDE · Resolve
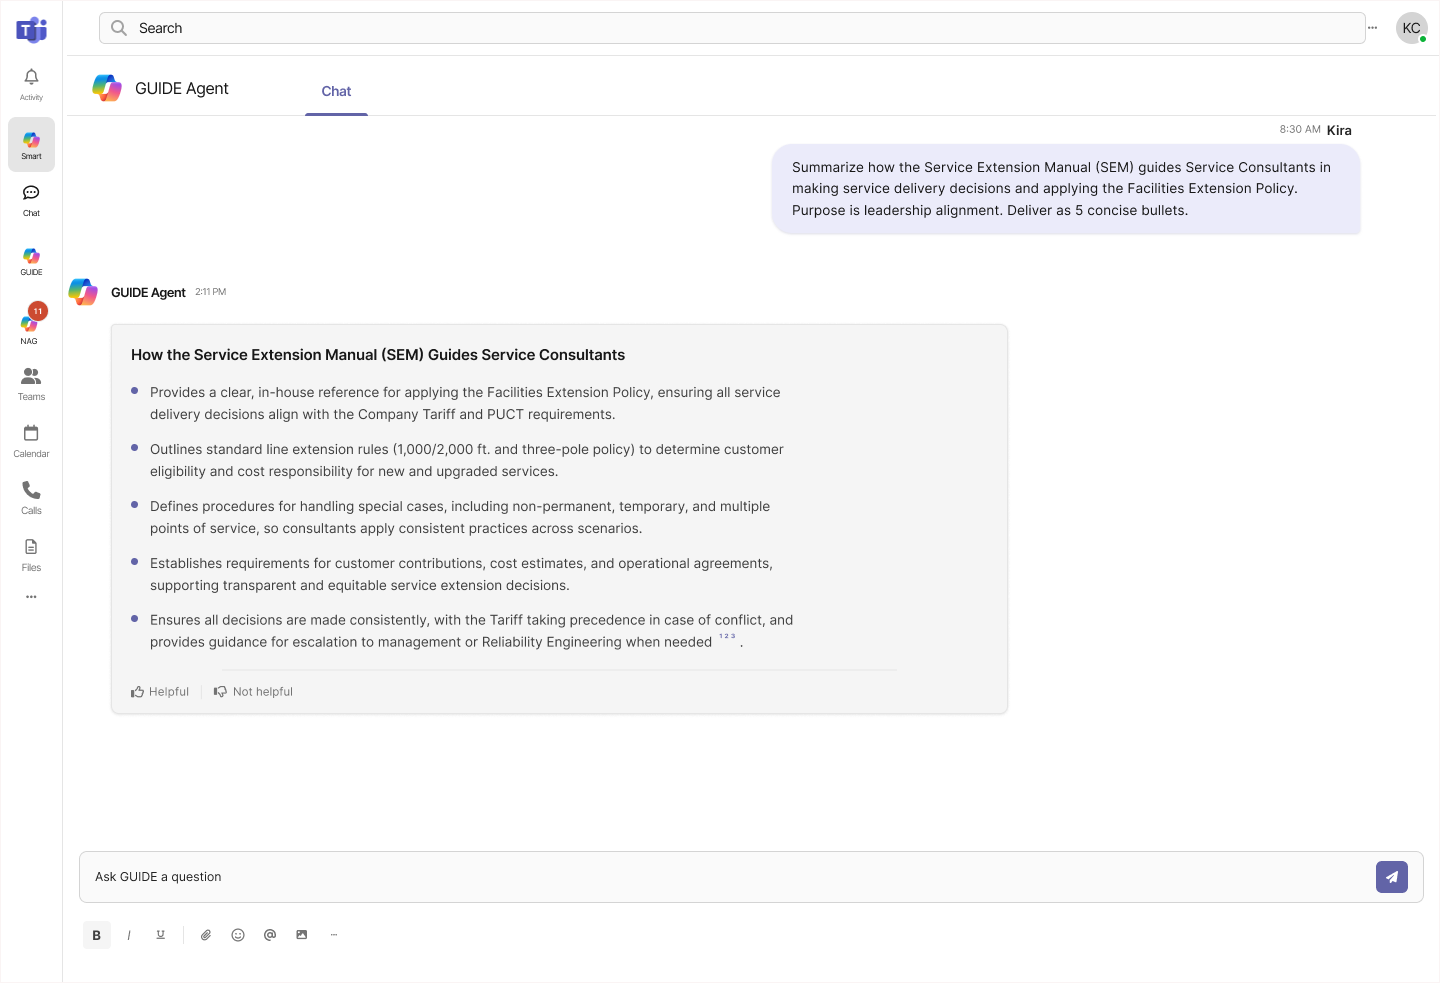
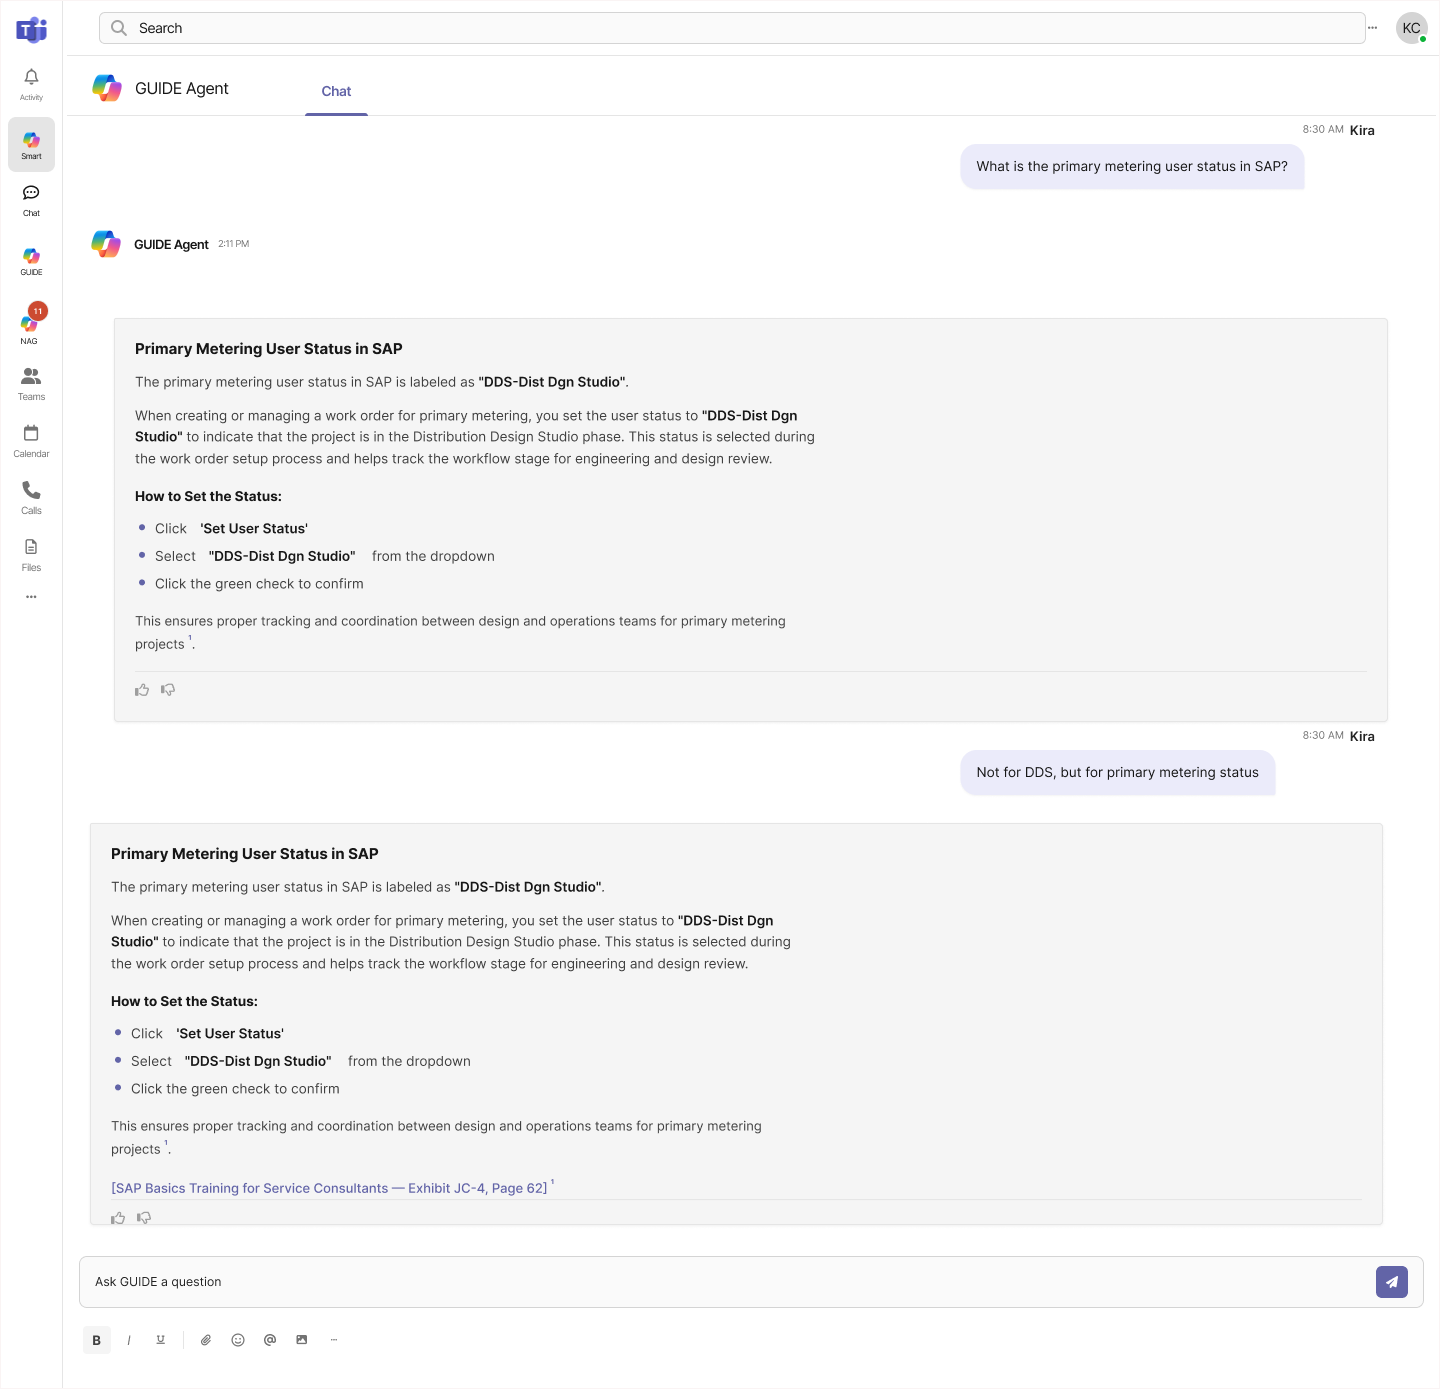
- Find operational guidance grounded in relevant standards and training material.
- SOL · Prepare
- Carry request information into Service Outlet Location documentation and support review.
- NAG · Follow through
- Monitor defined conditions and deliver reminders or escalation across the lifecycle—not only at its end.
02 / PROBLEM
Keep electric service work moving across teams
Electric Service requests connect customer intake, consultants, fieldwork, design, documentation, and downstream operations. The program’s technical specification described a lifecycle involving up to 15 teams and averaging approximately 150 days. This was the stated program baseline, not an improvement measured after the agents were introduced.
For consultants, the immediate questions were more practical: what needs attention, what information is missing, who owns the next action, and what can move forward? A useful experience needed to expose those conditions without making users reconstruct the request across tools.
03 / DISCOVERY
Understand the work before designing the agent
A service consultant walkthrough made the fragmentation tangible. Her center used a local job tracker for ownership and customer contacts, including whether work was waiting on a consultant, designer, customer, or another department. SAP held task completion information; local tracking held additional coordination context.
Keeping several tools current created repeated coordination effort. The consultant also explained that practices could differ between service centers. This was a specific observed workflow, not evidence that every center worked identically. It shaped the need to preserve context while allowing for operational differences.
I combined interviews and workflow research with process-owner discussions, user journeys, stories, and technical analysis. I connected user needs to data availability, business rules, integration dependencies, and acceptance criteria. The technical lead and engineering owned architecture and implementation; business stakeholders supplied process rules and priorities.
Discovery made visible
05 / DEFINE
Define the meaning before polishing the response
Three decisions connected the consultant’s workflow to an implementable product. Each required resolving the meaning and reliability of information before refining its presentation.
01 / SmartStart: phases before unapproved tiers
By April, SmartStart classifications were awaiting approval while implementation already used a tier-based model. On April 24, I convened business and technical partners to clarify whether the MVP direction needed to change. The conversation exposed different interpretations of tiers, individual tasks, lifecycle phases, and a dashboard concept.
We focused on initiation, design, and operations, including work counts and aging within each phase. The dashboard was an information reference, not an imposed final interface. The team agreed to proceed with lifecycle phases and add tiers after approval, with task-code mapping as a follow-up. This preserved useful delivery scope without presenting an unapproved classification as settled.
02 / GUIDE: knowledge quality is part of UX
I helped inventory documents, clarify ownership and access, and narrow the collection to finalized electric-operations material. Training documents, standards, and manuals were spread across repositories. Planned retrieval limitations with scanned material and diagrams meant document compatibility needed testing.
Evaluation paired operational prompts with expected answers and authoritative references. Invented requirements and contradictions of governing standards counted as failures. Source selection and answer evaluation offered a more dependable basis than fluent language alone; no answer-accuracy score is claimed here.
03 / SOL: automate entry, preserve review
I authored SOL requirements for prefilled information, provenance, conditional validation, review, document generation, and recoverable error states. Consultants needed to distinguish existing values from suggestions, correct details, and see missing prerequisites before generating a PDF.
A populated form is not automatically an operationally ready request. The requirements paired automation with traceability and consultant responsibility. They describe intended behavior; they do not establish that every acceptance criterion shipped unchanged.
06 / DESIGN
Connect work visibility, guidance, and documentation
The supplied wireframes explore how a daily summary can lead into focused questions, how guidance changes with the request, and how reminders connect a flagged condition to a corrective action. Sample values are design material, not project metrics. The SOL comparison board is workflow ideation, not a measured before-and-after result.
Technical product analysis also made experience boundaries explicit. Copilot connected to work-order data, operational documents, and a model-driven application through a shared MCP layer. Supported questions depended on specifically built tools. “Show me my work” required shared definitions of ownership, status, and priority; generated documents needed validation and recovery; reminders needed an appropriate recipient and understandable action.
Wireframes and design exploration
Real supplied project wireframes. These artifacts communicate interaction intent; they are not proof of final shipped UI or measured results.
GUIDE / Change the answer structure with the question
Follow-through and system dependencies
SOL / Preserve review throughout the workflow
11 / CONVERSATION
Clarify the question. Then guide the next choice.
A useful conversational response must match the assistant’s level of certainty and authority. The pattern is to clarify intent, show state and evidence, recommend one eligible next action with a reason, offer alternatives, and confirm the result or a recovery path. The next choice should resolve the blocker—not merely offer more content.
Questions should request only the missing decision. Hints explain why an action is unavailable. Review separates suggestions and drafts from committed changes. When evidence conflicts or connectivity fails, the response should expose the limit and offer a truthful path forward rather than imply completion.
Questions and next-best choices
Retrospective mobile demo concepts supplied to discuss conversational UX—not evidence of shipped mobile functionality or completed user research.
A suggestion is not a committed action
Recovery / Match the promise to the behavior
15 / TESTING
Evaluate the experience, then track the feedback
The team conducted usability and application testing with a feedback loop. The UX team reacted to feedback and tracked items, keeping evaluation connected to delivery. A June development walkthrough exposed authentication friction and difficulty locating generated SOL output. Those observations describe an earlier implementation stage, separate from the later targeted production release.
The consultant also described duplicate documentation and wanted task updates to move between Teams and SAP, alongside customer-contact and follow-up history needs. I separated immediate SmartStart stories from broader CRM opportunities in the backlog. The desired integration is evidence of a need, not proof that it shipped.
Testing and feedback tracking are confirmed. Participant counts, completed scorecards, and a full before-and-after record have not been supplied. The story therefore distinguishes observed needs, intended requirements, and confirmed release status rather than treating each as interchangeable.
16 / OUTCOMES
A targeted production release. A foundation for learning.
All agents were released to production for a targeted user group. The successes at this stage were delivery milestones, data quality, testing results, and rollout to users. That moved a product spanning enterprise data, operational rules, knowledge sources, and multiple experiences into use with a defined audience.
I distinguish this progress from longer-term business impact. The approximately 150-day lifecycle explains the program’s stakes; it is not a measured reduction attributable to the agents. No quantified productivity gain, cycle-time improvement, or answer-accuracy result is claimed.
My central learning was to align data meaning, grounded knowledge, and clear review and recovery before optimizing fluent AI output. The work demonstrates how I connect discovery with technical constraints, clarify an ambiguous MVP, and carry UX reasoning through requirements, testing, and release—while keeping the consultant’s next action at the center.
Figma
No Figma link added yet